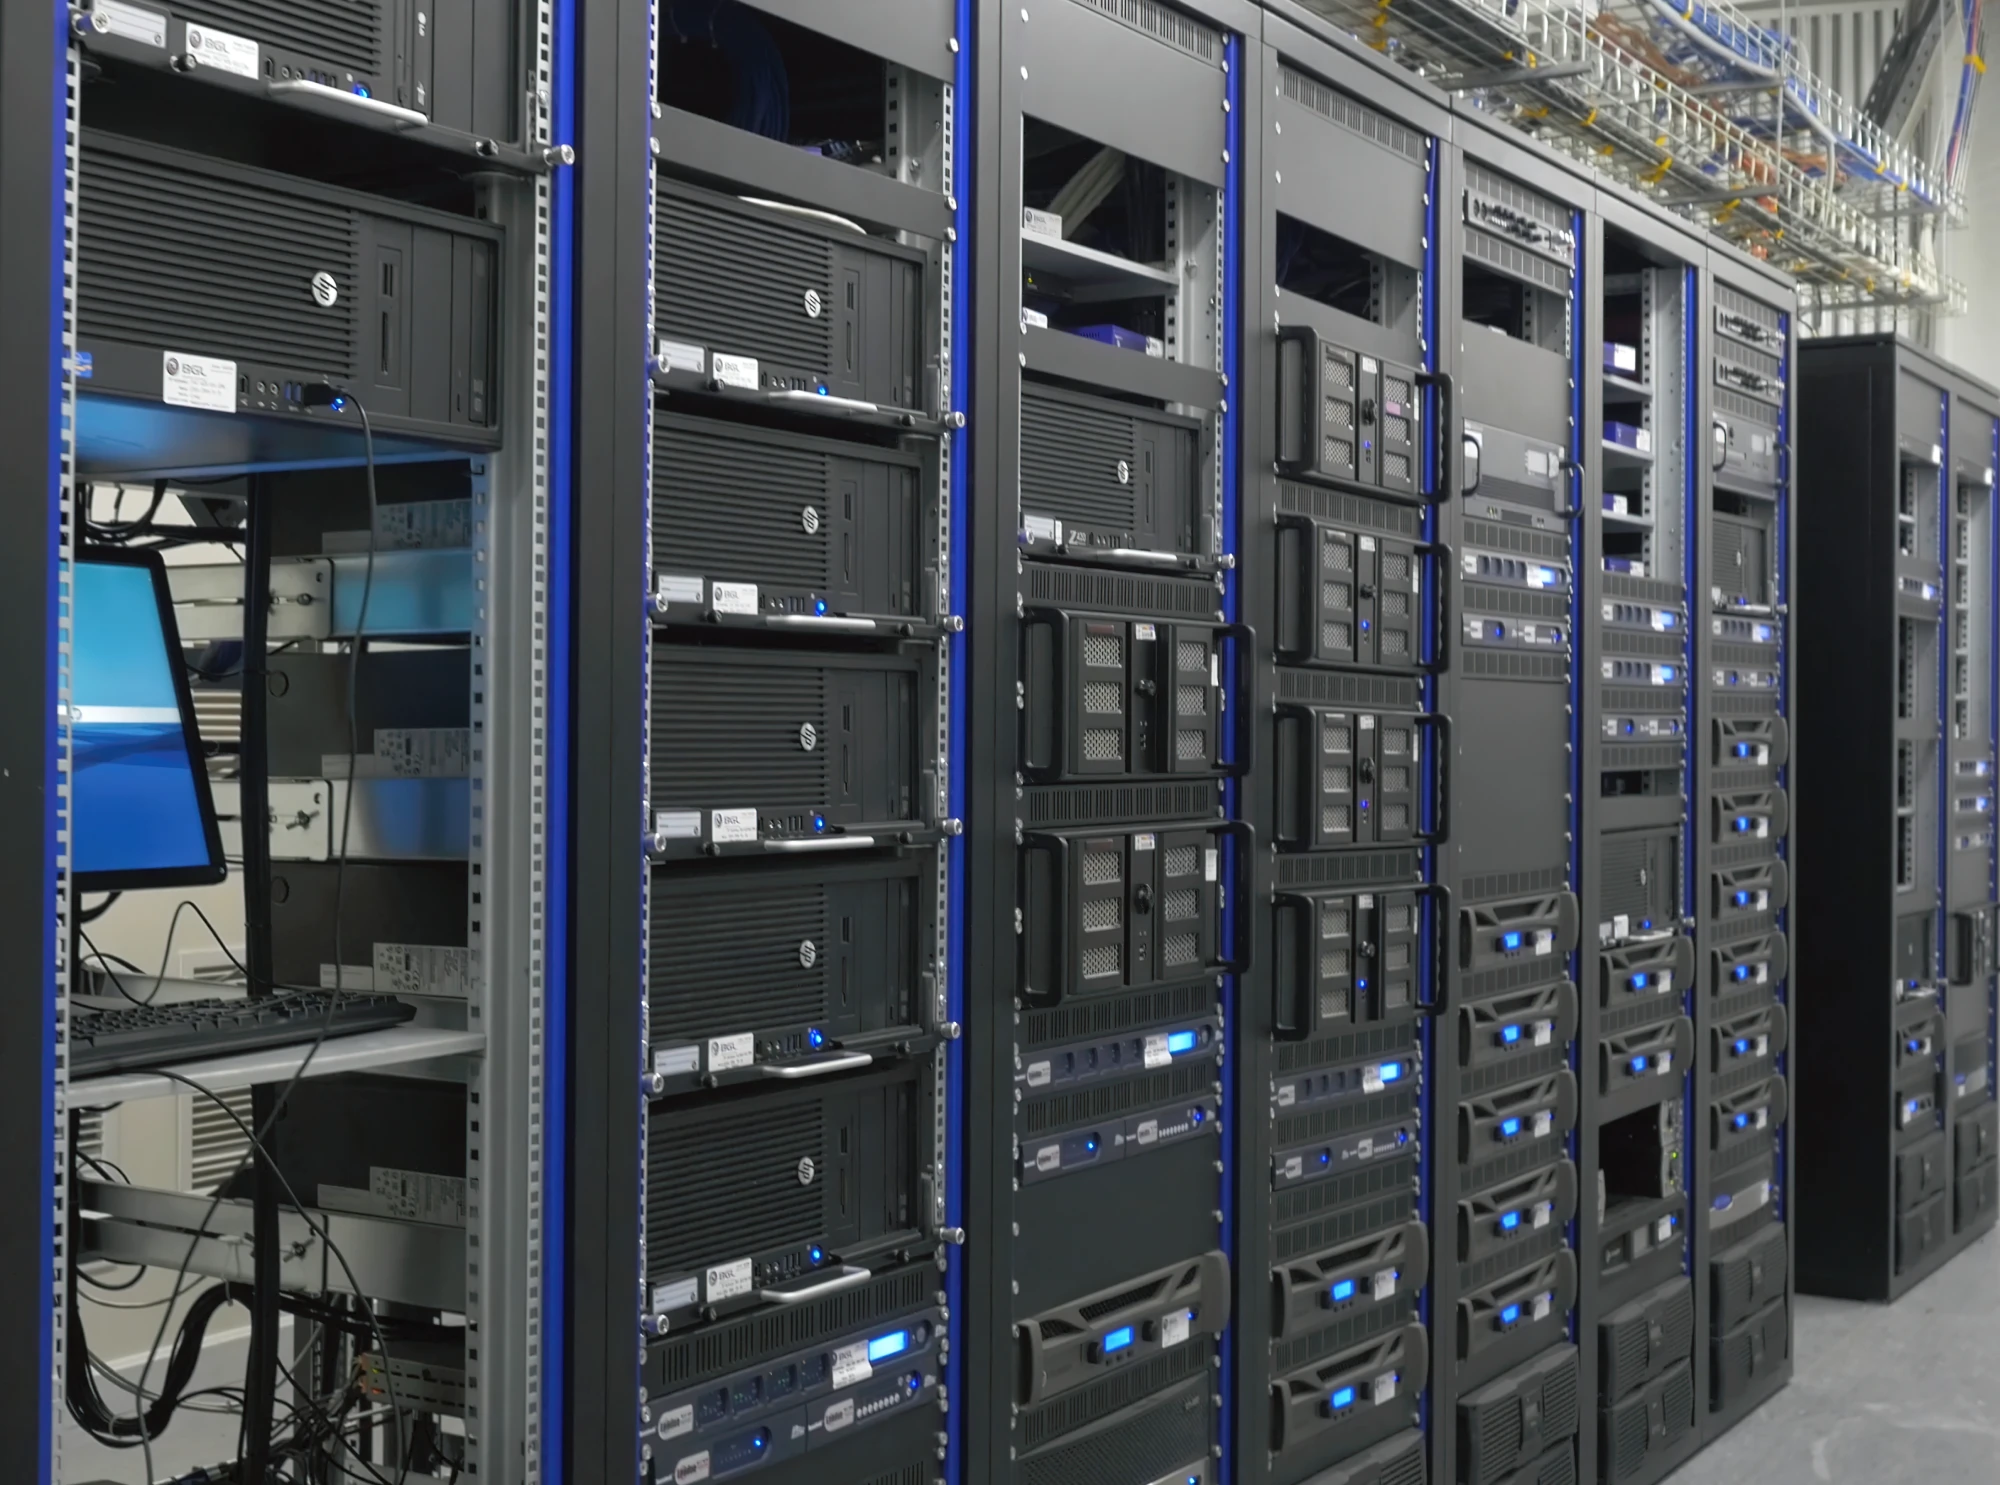
Your own AI instead of someone else's cloud: with a GPU server you run language models, image generation or machine learning pipelines on hardware that belongs to you alone – with predictable costs and without your data leaving Europe.
Built for AI
Current NVIDIA data centre GPUs with plenty of graphics memory – for training, fine-tuning and fast inference.
Your data stays in the EU
Hosting in Austria and Germany instead of US hyperscalers – important for customer data, trade secrets and the GDPR.
Personal advice
We configure your server for your use case: which GPU, how much VRAM, how many cards – explained honestly and clearly.
Predictable monthly costs
A fixed monthly price instead of per-minute cloud billing – usually much cheaper than cloud GPU instances for continuous use.
Our GPU models
| GPU | Graphics memory | Strengths |
|---|---|---|
| NVIDIA RTX PRO 6000 | 96 GB GDDR7 | Blackwell generation, excellent value for inference, mid-sized LLMs, image generation and rendering |
| NVIDIA H100 | 80 GB HBM3 | The standard for AI training and fine-tuning, very high memory bandwidth |
| NVIDIA H200 | 141 GB HBM3e | For large language models and long contexts – more model fits on a single GPU |
Availability, number of GPUs per server and configuration on request. Multi-GPU servers are also possible.
Use cases
- Run your own LLMs (e.g. Llama, Mistral, Qwen)
- Fine-tuning on company data
- RAG systems & internal AI assistants
- Image, video & speech processing
- 3D rendering & simulation
- Research & scientific computing
Software stack
On request we deliver the server with drivers and the CUDA environment pre-installed.
Which GPU do I need?
The most important factor is graphics memory (VRAM): the model must fit into it completely to run fast. As a rule of thumb, a language model in 16-bit precision needs about 2 GB of VRAM per billion parameters, quantised (e.g. 4-bit) much less. A 70-billion-parameter model runs well quantised on an RTX PRO 6000; for training or large unquantised models, H100 or H200 – or several GPUs – are the better choice. Our guide GPU servers for AI: what really matters explains this in detail.
GPU server instead of cloud?
Cloud GPUs are handy for short experiments. But if your models run continuously – an internal chatbot or an AI feature in your product – hourly billing quickly becomes expensive. A rented GPU server has a fixed monthly price, the hardware is yours alone for the term, and your data sits in a European data centre instead of with a US corporation.
GPU server FAQ
How much does a GPU server cost?
That depends heavily on the GPU model, the number of cards and the term. We are happy to prepare a non-binding quote – just tell us briefly what you are planning.
Can I rent a GPU server for just a few months?
Yes, talk to us. Depending on model and availability shorter terms are possible; longer terms are usually cheaper.
Do you help set up the AI software?
Yes. Besides drivers and CUDA we can also set up inference servers such as vLLM or Ollama. As software developers we also support you in integrating AI into your applications.
Is a GPU server GDPR-compliant?
Yes. Your servers are located in data centres in Austria or Germany and are looked after by an Austrian company. Your data does not leave the EU – unlike with many AI cloud services.